Decibri
A unified audio library for voice-based intelligent agents
Introduction
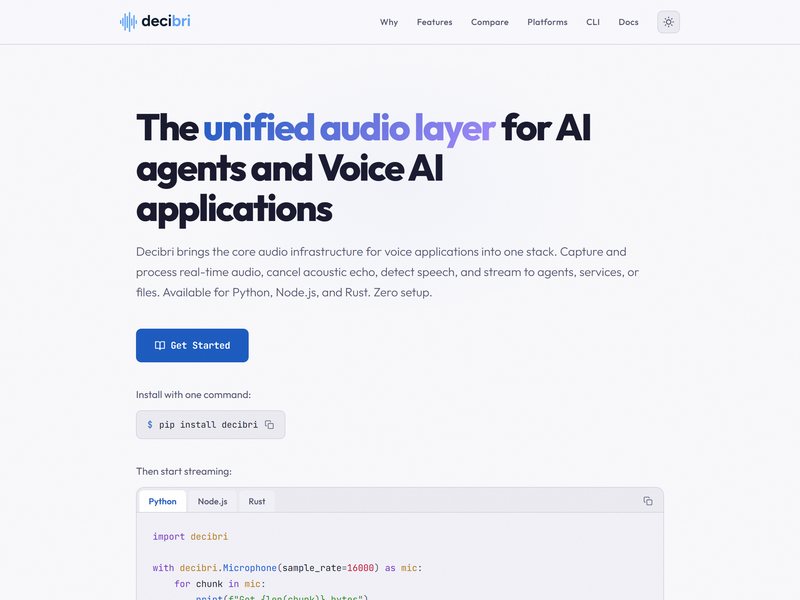
Anyone working in the field of voice applications knows that the most challenging aspect, beyond developing the model itself, is dealing with audio data: how to capture sound through microphones, how to reproduce it via speakers, how to eliminate echoes, and when exactly it can be determined that a user has started speaking. Decibri has integrated all these aspects into a single library.
It provides real-time microphone input, speaker output, acoustic echo cancellation, and voice activity detection. The captured audio can be streamed directly to intelligent agents or cloud services, or it can be saved in files. The same set of APIs is used for Python, Node.js, and Rust.
The learning curve is extremely low. In Python, simply execute the command `pip install decibri`, and you can start reading data from the microphone after writing just a few lines of code—no additional system dependencies are required.
This is purely developer-oriented infrastructure—it comes without any user interface, nor does it include speech recognition or synthesis models; those components need to be integrated by the developers themselves. It will be particularly useful to those who are working on building voice intelligent agents or have already dealt with the various audio interfaces provided by different platforms.